Thousands of hours of first-person video, on demand.
We collect first-person video of real work tasks, captured by professionals using head-mounted cameras across Latin America, South Africa and the Middle East. Built to train the most demanding AI models.
Standing capacity across the network.
Your team defines the tasks, the environments and the volume. We deploy qualified members from our network of collaborators and deliver a constant stream of high-quality egocentric video.
Robot foundation models are trained on three layers of signal. Most vendors claim all three and are thin on each. We produce the human layer — the demonstration signal — and we produce it end to end, from recruiting the person to the signed release.
Simulation, scene reconstruction and context that world models train against.
First-person capture of real work. The source signal for how people actually move, reach, grip and recover from mistakes.
Teleoperation logs and teacher-follower demonstrations that bridge human intent into robot execution.
Engineered to capture, process and deliver thousands of hours of egocentric footage per month. The pipeline flexes for volume spikes and hard deadlines instead of breaking under them.
Trained, equipped collectors across emerging and key international markets, giving you demographic, environmental and domain coverage that a single-country vendor cannot reach.
Custom recording protocols: specialised head-mounted gear, multi-modal sensor logging (IMU, audio, depth), script-driven task execution, and organic unscripted daily workflows.
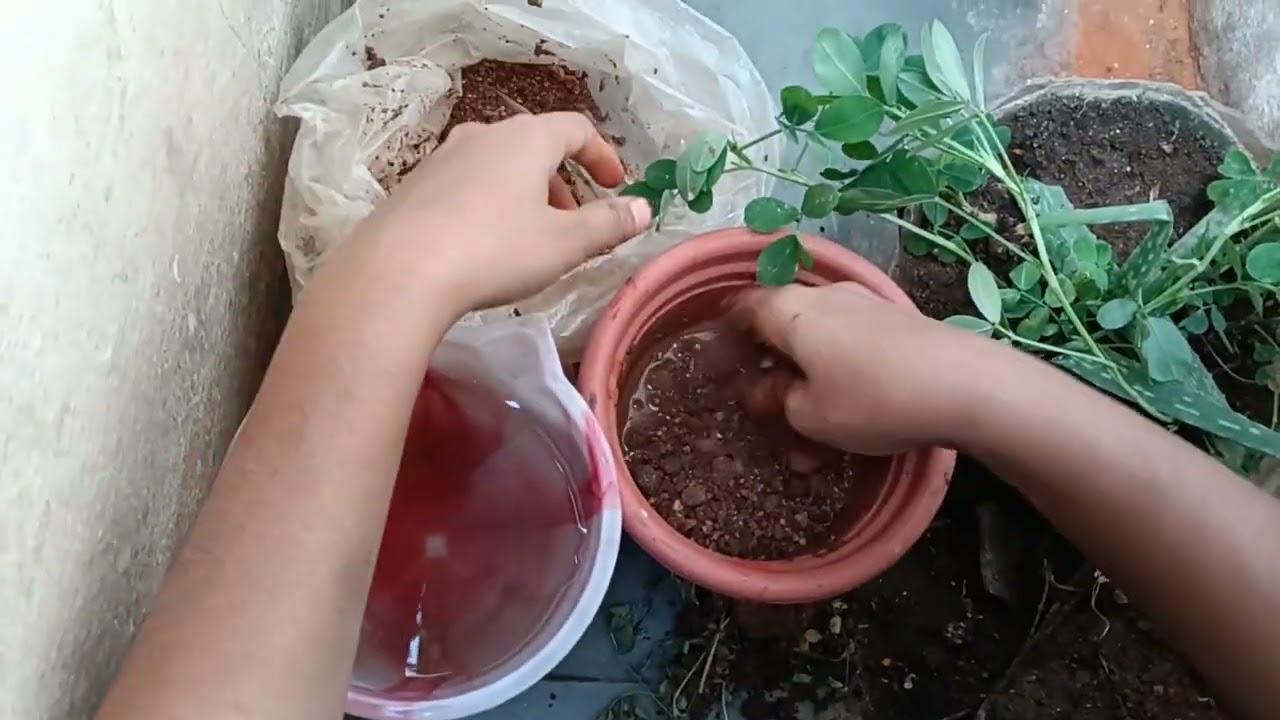
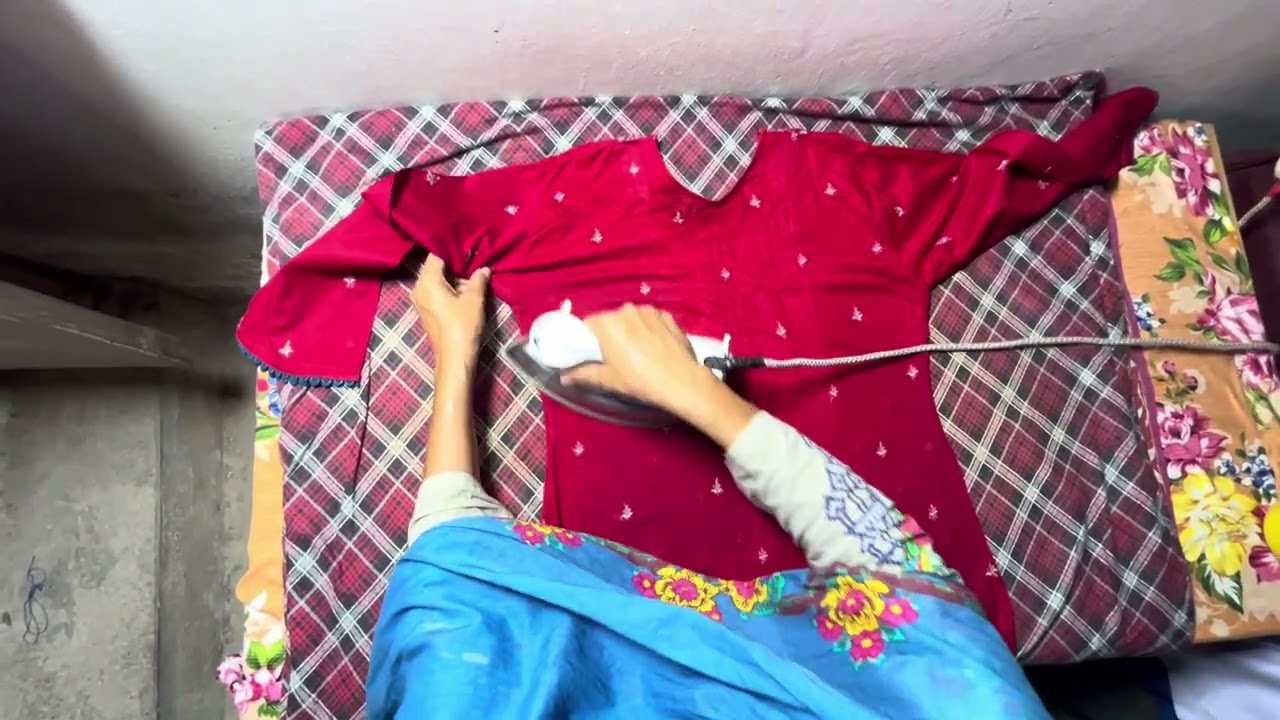
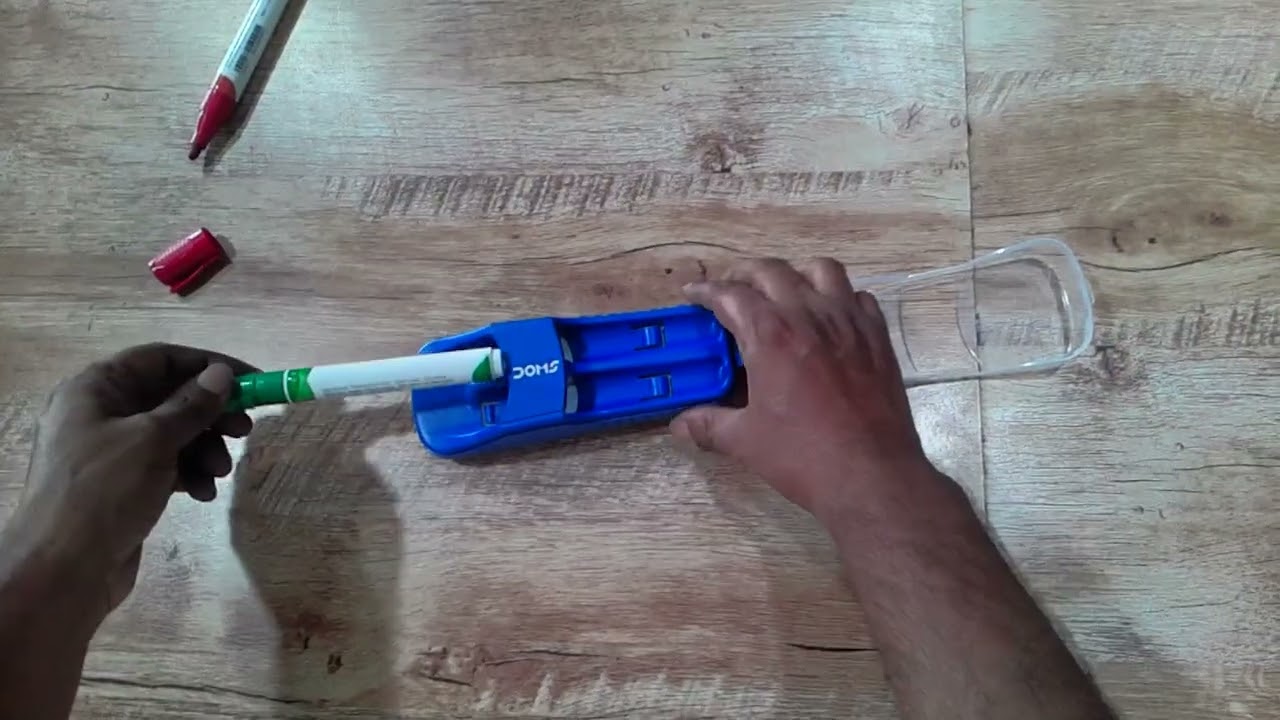
Unedited clips straight from the network — head-mounted, shot on the contributor's own phone, in their real workplace. No staging, no reshoots, no cleanup. Tap one to preview it, or watch all three at full size below.
Tap a clip to play it in colour.
Want the full sample pack, with metadata and the consent record attached? — it is free.
Fifteen work domains, eighty-four catalogued tasks and thirty-two countries already running. Everything below is live in the network and can be commissioned today.
Hands-on work in commercial settings — the cramped, cluttered, badly-lit places that break models trained on clean lab footage. All fifteen are live in the network and can be commissioned today.
Tap any domain to see its tasks. Need a domain that isn't here? We recruit for it. Two to three weeks to stand one up.
Our standard spread across the network — balanced so a model sees variety rather than one kitchen a thousand times, and weighted toward the regions most datasets under-sample. Every slider moves: tell us the mix you want and we build the run to it.
Share of a standard 5,000-hour programme. Configurable to your spec at no extra cost.
Thirty-two countries with city leaders in place and contributors onboarded in the capture app. Any of them can be switched on for a commissioned run, and new ones take about three weeks to stand up.
Adding a country takes about three weeks: recruit a city leader, onboard contributors, secure business permissions.
Tasks, scenes, minimum clip length, camera placement, and what must never be captured. We turn the spec into a task list the contributor sees on their phone before they hit record.
City leaders recruit inside the trade and secure written permission from each business. People record their own shift through our app: pick the task, hit start, it uploads by itself. Nothing is assembled after the fact.
Every session is rated by a human before it counts. Unusable footage is rejected and never paid for. Faces, documents, screens and anything you excluded are handled to your rules.
Clips with task and scene labels, country, device, duration and timestamps, plus the consent and payment record behind each one. Your bucket, your structure, your manifest.
Head-mounted first-person video shot on the contributor's own phone, in their real workplace. Exact device model recorded per clip so you can filter or stratify by sensor.
Step segmentation, hand-object interaction tags, affordance and failure-mode marking, or a taxonomy you hand us. Priced per hour on top of capture.
Encrypted transfer to your cloud bucket with a manifest and dataset card, or a shared drop we hold for the length of the engagement. Formats to match your ingestion.
Egocentric footage is filmed inside someone's workplace, often around their coworkers. Done badly, it becomes your problem long after delivery. So we built the paperwork before we built the library.
Each contributor signs an agreement before recording and is paid per approved hour at a rate they know in advance. They can check what they have earned in their own dashboard, any time. Nobody works for exposure.
Nothing is filmed on a business's premises without written permission, and the owner can stop it at any moment without giving a reason.
No minors, no documents, no screens, no internal pricing, no identifiable customers. Those rules live in the signed agreement, not just in the training deck.
For any clip we can produce who recorded it, where, when, on which device, under which agreement, and what they were paid. Full chain of custody on request.
Every clip we sell can be traced to a person who signed an agreement, a business that gave written permission, and a payment that went out. That is the part your legal team will ask about — and the part most of this industry cannot answer.
Most teams start with a free sample pack to check the fit against their pipeline, then commission a run built to their spec.
Two to three weeks from brief to first clips in a domain we do not already run. In a domain we already cover, first clips land in days.
Yes, free. Tell us the domains and we send a sample pack from the library carrying the same metadata and consent record a full delivery does.
We own it. The contributor agreement assigns it to us, explicitly including use for AI training, and they are paid for that. You receive a clear licence for training and evaluation, with the provenance documentation behind it.
The contributor's own phone, head-mounted. We log the exact model per clip so you can filter or stratify by sensor. If your model needs specific hardware, we equip the run for it.
Thirty-two countries, with the deepest bench across Latin America and a second cluster in Asia-Pacific and the Gulf. That matters because the big coverage charts in this industry are dominated by two or three countries. Different regions mean different tools, layouts, product mixes and working practices — precisely the distribution shift that breaks a model in deployment.
On request: step segmentation, hand-object interaction tags, or your own taxonomy. Every clip already ships labelled by domain and task from a fixed catalogue.
Per approved hour. It depends on the domain, how hard it is to recruit for, and whether you need annotation. Tell us the volume and we come back with a number.
Exclusions are written into the signed agreement and enforced at review: no minors, no documents, no screens, no identifiable customers. Face and object redaction is applied to your rules before delivery, and anything that breaks the rules is rejected and never paid for.
Pick your domains, say roughly how many hours you need, and we come back within one business day with samples and a price.
Five fields. We reply within one business day with a sample pack and a price.
We'll come back within one business day with samples and a price. If it's urgent, reply to the confirmation and say so.